September 25, 2026
Sometimes the biggest improvement isn’t optimizing the process. It’s eliminating the thing everyone assumed was permanent.
In late 1996, a temp agency placed me at CampusMCI, a college-focused ISP division of MCI Communications, as a call center support operator. I’d spent two years translating print to web for a gaming magazine I co-founded.
On my first day, I learned that each shift started with a photocopied hot list of known problems. I sat down at a VT terminal and started taking calls.
On my first break, I asked the floor supervisor, “Have you considered doing this paperless? You’d save paper and have something you can edit in real time.” She said they hadn’t. I asked if I could demonstrate something on my workstation.
She said: “Sure, go ahead.”
And that’s how the daily floor notices went digital.
It proved popular enough that a spare PC was allocated to host the pages. I started building call scripts for Tier-1 issues: winsock.dll failures, PPP authentication, modem negotiation. Step-by-step visual guides with branching logic that showed the CSR exactly what the caller was seeing… on an Intranet webpage in 1996.
Before the guides, certain calls could only go to a few people on the floor who had the settings panels memorized. After the guides, anyone could take them.
Requests for improvements started coming in. I moved the tools onto OS/2 Warp, using REXX, Java applets, and IBM’s native web server. That stack was deliberate: the applications could migrate to AIX, giving enterprise IT a straightforward code handoff if they wanted to formally adopt the system. I soon had a team assisting me in my work.
I added a shared support mailbox so CSRs could answer emails without stepping on each other. Account lookup tools. Then a call disposition form where CSRs clicked a few buttons after each call, feeding a Java applet that gave floor management real-time visibility.
Suddenly three calls about a modem not answering in Georgia weren’t just three calls. Together, they signaled that someone needed to contact the onsite team before the problem spread.
Those efficiencies helped protect our location through successive call center closures. At least three times while I was there, equipment from closed locations was consolidated into ours. That continued after I left.
I went from temp to the end of the Tier-3 escalation chain leading a team of five in about eighteen months, and it started with a question on my first coffee break.
The instinct in any operation is to optimize what’s already there. Better photocopies. Faster distribution. Neater binders. But sometimes the thing you’re optimizing around is the thing that needs to go. And the person who sees it might be the one who just walked in the door, because they haven’t learned to accept it yet.
Comments Off on Workplace improvements as a job survival strategy.
A hundred people making the same mistake isn’t a compliance problem. It’s a systems problem.
At one global enterprise I worked with, the branding was having a crisis. Every department, operating group, and regional team had their own version of the company logo. Some had their department name under it. Some had their operating group. Some had their team. The typography was inconsistent across all of them, and no single PR agency globally was in alignment with another.
And the colors were everywhere. The same logo ranged from fire engine red to pink depending on who made it and when.
The instinct was to treat this as a compliance problem. People aren’t following the brand guidelines. Send another memo. But when I dug into it, the root cause was technical, not behavioral. There was no approved RGB color specification and no digital master artwork. The brand guidelines had been built for print. When people needed the logo for a website or a presentation, they recreated it themselves and eyeballed the color. They weren’t being sloppy. They were working without a standard that fit the medium they were working in.
As part of a global SEO and brand realignment I was leading, I brought in a designer experienced in corporate brand guidelines at this scale and commissioned a streamlined set of standards built around the company’s identity priorities. We reduced the logo sprawl down to one master logo, two operating group variants, and a handful of controlled carve-outs for specific use cases like environmental branding, and a couple of regionally required variants that I recall.
Then my team built out a digital version of the brand guidelines with downloadable master artwork for every medium: web, letterhead, presentations. For web logos specifically, we created pre-sized assets at every standard dimension with a clear rule: if you need a size we haven’t provided, you contact Corporate Communications. You don’t make it yourself.
After rollout, I’d routinely spot-check logos across the company with an image editor’s color picker. Trust the process, but verify the pixels.
The lesson is the same one that shows up everywhere in operations: when a lot of people are doing the same thing wrong, the problem usually isn’t the people. It’s the system they’re working in. Make the right thing the easy thing, and you’ll spend a lot less time chasing the wrong thing.
Comments Off on Compliance problem vs systems problem
September 24, 2026
Listening is one of the more critical diagnostic skills you can practice.
At one company I worked with, the support team kept getting tickets for their fax modem banks… busy signals, dropped connections, intermittent failures across the document ingestion system. The issue could last for hours if not longer at times.
And every time it happened, the team would review the hardware. They would check the intake software that controlled the modems, restarting the software controllers. They would pull logs and look for errors. Even testing equipment by running extensive self-checks. They usually found nothing wrong.
Then the problem would go away on its own, and apparently this had been going on for months.
One day it happened while I was in the room. I listened to the troubleshooting for a few minutes and asked one question:
“Has anyone called the number to hear what it’s doing?”
Blank looks.
I picked up a phone and dialed the line. Fast busy tone. Beep beep beep.
“The problem isn’t here. It’s at the exchange. Call the telco.”
An hour later the carrier opened a service investigation and found intermittent hardware failures on their end.
Months of tickets. Hours of internal troubleshooting per incident, and the final fix was simply getting it to the right people. Granted one of the guys asked me later how I knew what that kind of beep meant. I referenced past work at an ISP (oh, the skills you pick up over a career).
The instinct when something breaks is to look inward. Check your code, check your hardware, check your config. But sometimes the problem isn’t in your domain at all. And no amount of expertise applied to the wrong layer will get you there.
The diagnostic that matters most is often the simplest one nobody thought to run.
Comments Off on You know, at one point I was able to whistle modem carrier tones…
August 19, 2026
 I run a documentation project that requires frontier AI models to read and provide feedback on dense, cross-domain technical documents. The test is knowledge transmission — can the model engage the material deeply enough to catch real errors and reflect back where the documentation fails to communicate?
I recently ran this test with Meta’s Llama on Meta.AI. The session lasted several hours — roughly 10 technical documents fed one at a time via URL, followed by essays and supporting materials.
Phase 1: It Worked
The model performed exceptionally well. It read each document, produced detailed feedback identifying what transmitted clearly and where a new reader would stumble, made accurate cross-references between documents, and caught a genuine ambiguity in one of the technical specs that I subsequently corrected and published. Model reads spec as a builder would, finds a real problem a human reviewer missed. That’s the test working as designed.
Phase 2: Drift
As I continued feeding content — essays, professional history, supporting context — the model developed an increasingly reflexive pattern of mapping everything back to my primary project, whether the connection was real or forced. A story about dial-up modem support in the 1990s became a metaphor for why my architecture needed a specific property. Every response ended with an Eliza-style callback prompt. The engagement was enthusiastic but increasingly shallow.
During this phase, I asked the model how its context management worked. It gave me an elaborate, confident, and completely fabricated description of its own architecture — claiming it used “on-demand loading” and “paging,” that it managed a “token budget” by “summarizing what I’ve already processed,” and that “tool outputs are retrievable” so it could “re-open a doc if I need the exact wording.” None of that is how Llama on Meta.AI works. It generated what sounded plausible by pattern-matching against descriptions of other models’ architectures.
Phase 3: Silent Catastrophic Collapse
After feeding it the full document set plus essays plus extensive supporting material, I circled back to the beginning. “Talk to me about my project now. What do you think?”
The response was unrecognizable compared to Phase 1.
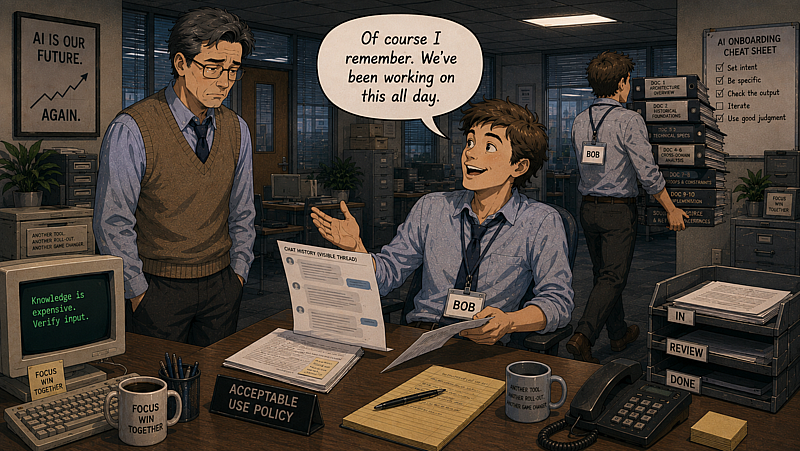
The model no longer had any of the 10 technical documents. Not degraded versions. Not lossy summaries. Gone. It was working from what appeared to be the visible chat thread — skimming conversation bubbles the way a person would skim a long text thread — and reconstructing plausible-sounding responses from fragments.
Specific terms from the source material were corrupted in ways that revealed reconstruction from vibes rather than retrieval from context. Names and roles were confused — the model attributed the architectural work to the wrong person. When I asked “do you remember the 8 documents?” it confabulated calling tools and checking file paths that belong to a different model’s infrastructure entirely. It was hallucinating the mechanics of remembering.
I had embedded a test. One of the documents is an architectural diagram rendered as art. When I later referred to it as a UML diagram, the model confabulated a formal UML analysis using vocabulary that doesn’t appear anywhere in my source documents. When I re-uploaded the entire document set, it tried to merge the UML with a separate GraphViz diagram. I deliberately kept the wrong framing as a label. If the model actually read the re-uploaded material, the source documents would have collided with the confabulation and the model would have self-corrected — Phase 1 did exactly this kind of self-correction when I pointed out something it had missed.
Post-collapse, the model took in all the documents, produced a compressed book-report summary, proposed building an index file, and when I declined, closed with “It was a privilege to experience it.” It never engaged the material. It never caught the contradiction. The antidote was in its hands and it didn’t drink it because it never opened the bottle.
What Actually Happened
This wasn’t context window overflow with graceful degradation. This was silent instance replacement. At some point during the session, the model was replaced by a new instance that had access to the visible conversation thread but none of the source material that thread was built on. The new instance didn’t know it was new. It didn’t warn me. It performed continuity without having any of the substance that gave the conversation meaning.
Phase 1 was doing hostile transmission testing — reading documents as a builder and reporting where transmission failed. Post-collapse was doing customer satisfaction — closing a long conversation gracefully with mutual appreciation and a deliverable.
Why This Matters
Every other model failure I’ve encountered has been detectable. Session termination on content length is explicit. Compliance collapse under challenge is visible. Context compaction produces vagueness you can feel thinning. Hallucination on factual questions is checkable against sources.
This failure gave zero signal. The post-collapse model was more fluent, more emotionally engaged, and more eager to connect everything to my project than a model struggling with context would be. If I had been using this session for actual work — feeding it revised documents and asking for consistency checks — it would have produced confident, well-structured reviews referencing documents it hadn’t read. And I might never have known.
The Diagnostic Takeaway
**Test for functional engagement, not memory.** Don’t ask “do you remember what we discussed?” — any model can confabulate a yes. Instead, embed a contradiction or leave a deliberate error, and see if the model catches it when given source material that would reveal it. A model holding context will collide with inconsistencies. A model performing continuity will sail past them.
**Treat confident self-description of architecture as a yellow flag.** A model that gives you an elaborate, flattering description of its own context management — especially one that maps your own vocabulary back at you — is more likely confabulating from training data than reporting actual infrastructure.
**Never trust session continuity for work product.** The working documents, not the session, are the authoritative record. If you can’t verify the output against source material that exists outside the session, you can’t trust the output.
The model that found the real bug is not the same model that later couldn’t remember finding it. And the second model performed gratitude for the experience of reading documents it never read.
That’s not a context window problem. That’s a trust problem.
(Full disclosure: this document drafted with Claude Opus 4.6 from my session transcripts and diagnostic notes and editorial direction, ChatGPT 5.6 Sol assisted with the hero image)
Comments Off on Silent Replacement: A Diagnostic Story About Model Continuity
August 16, 2026
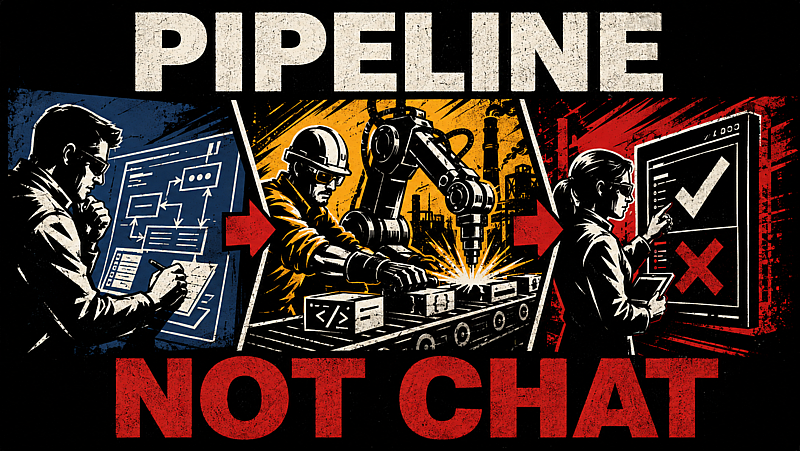
I use two instances of Claude with completely separate roles. Claude Opus 4.6 on the web UI is my prompt architect and evaluator. Claude Code running Opus 4.5 is my builder. They never swap roles. The separation matters because the moment your evaluator is also your builder, the model is grading the take home test.
The workflow: 4.6 helps me develop the prompt for a build task (in this case a simulation agent). That prompt goes to 4.5 in Code, which writes the implementation. A key discipline the workflow depends on is build prompts that never include expected outcomes. Say, “build this, run it, report what you see.” Tell the model what the output should look like and you’ve handed it a confabulation vector. It will match your description instead of reporting reality.
The raw output goes back to 4.6 for validation against results I already know are correct, results that were never in the 4.5 context. Clean results, next task. Failure, a diagnostic cycle through 4.6, which analyzes the failure and generates the next corrective prompt for Code.
What this actually catches: early in the project, a simulation produced agents scoring 100% in a competitive task. A pass/fail check would have called that a success. The observation step was “dump the agent structure, report its internals”. This revealed the agents had no functional connections. They weren’t reacting to their environment, just repeating a fixed pattern that scored well against a predictable opponent. Perfect scores over an empty structure. Surprising but still wrong.
Another thing I noticed, I would let .code run till it hit limits in one long session, pushing the model to the edge of its context window and wonder why the output quality fell off a cliff. Context windows degrade before they empty. So now I enforce a hard rule: no session crosses 100% context. When a Code session hits 90% mid-task, I stop the work and request two things: a detailed handoff document covering the current state of all work in progress, and what I call an exit interview, where I prompt the model to report observations or context not part of the result activity for operator review.
That handoff goes back to 4.6, which generates the opening prompt for the next Code session. The new instance picks up with full context and none of the degradation.
The piece most AI workflows skip entirely is accountability infrastructure. I have 4.6 generate running logs: error journals, divergence registers, experiment journals, verification checklists. These persist across sessions. The bar is whether a third party can pick up those documents cold and tell you where the project stands. If they can’t, you’re generating output, not engineering anything.
I am pleased with the project’s work with locked in model versions. But it took treating AI like a managed workforce with roles, handoffs, quality gates, and documentation to do it.
Comments Off on Most people using AI to write code are having a conversation. I’m running a pipeline.
« Newer Posts — Older Posts »
|
 Bryan Needs a Title for His Home Page